









OpenAI’s 700W Jalapeño ASIC outpaces 1,400W Nvidia flagship GPU — claims up to 1.9x throughput per kilowatt and 3.6x lower latency, co-developed with Broadcom
Nvidia's Vera Rubin wasn't in the comparison.
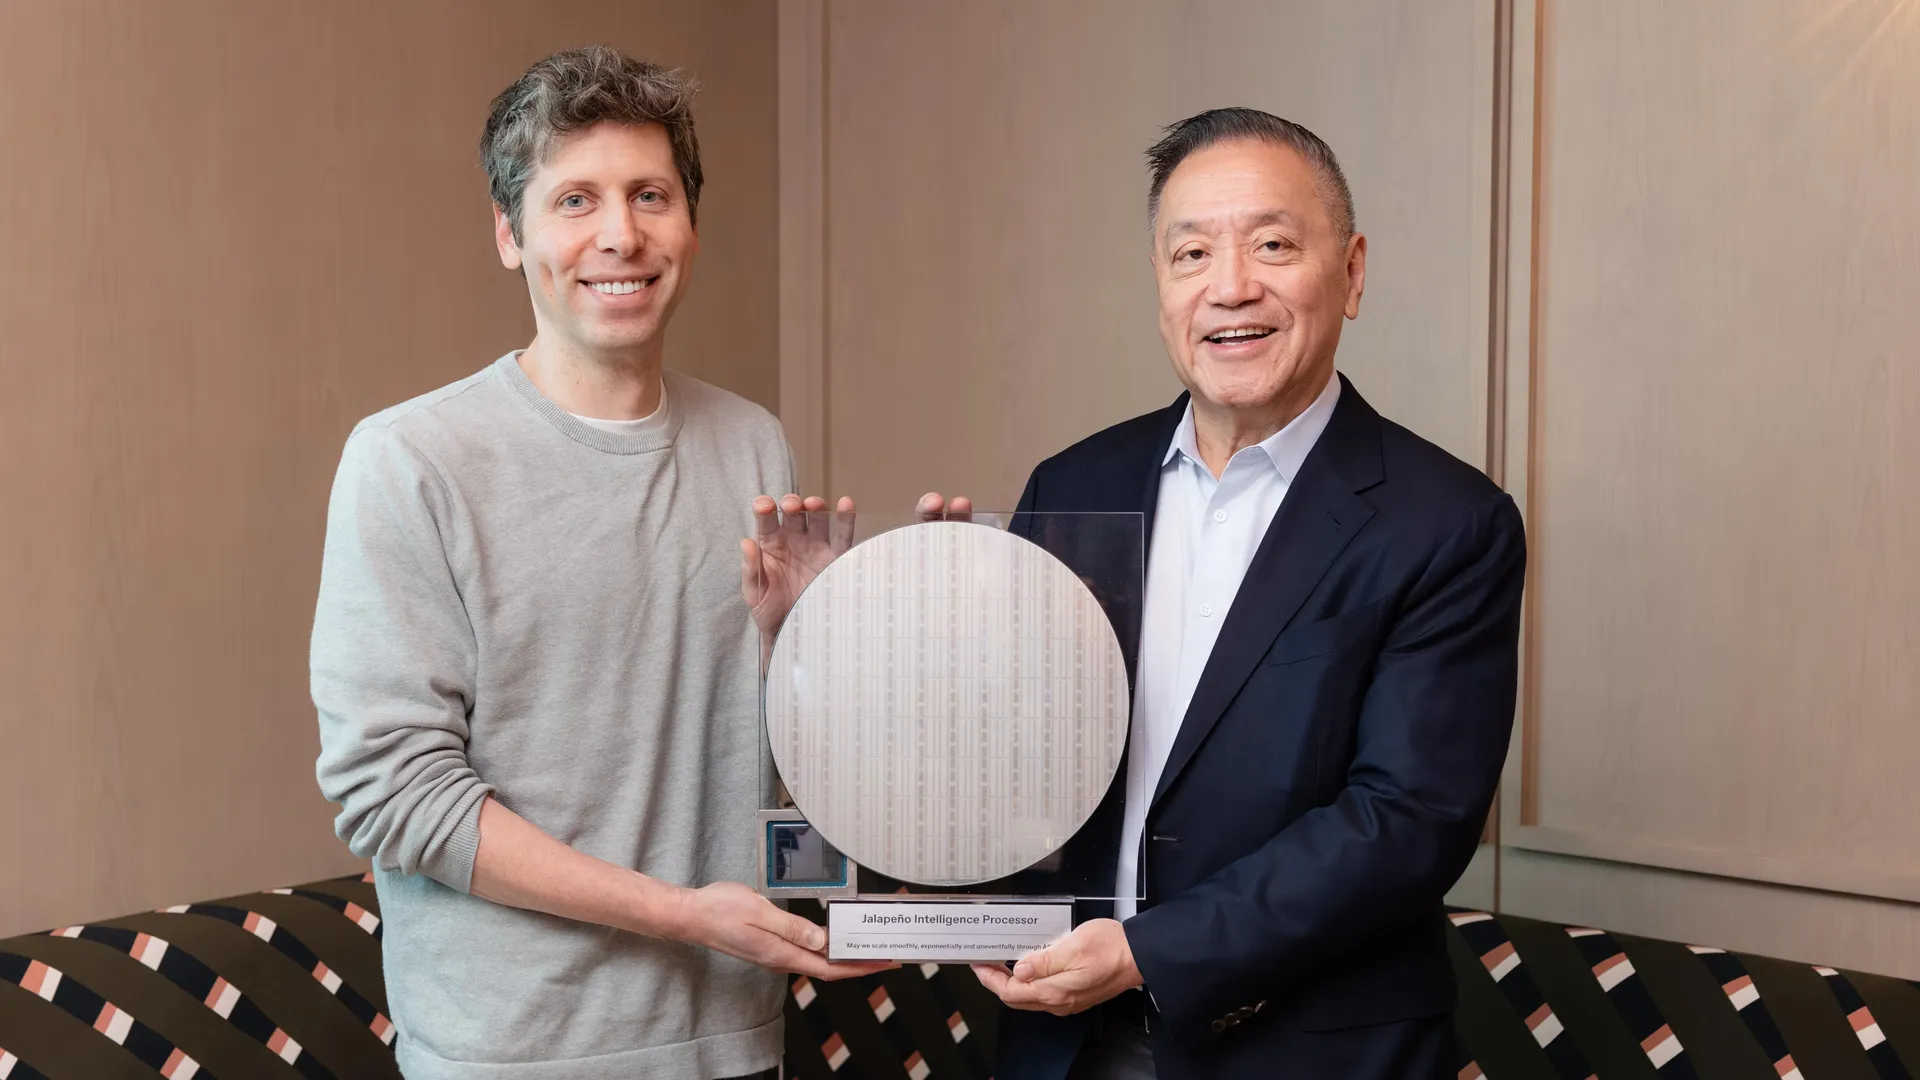
Just over one week after Nvidia agreed to backstop up to $105 billion in financing for its data centers, OpenAI arrived at Hot Chips on Tuesday with benchmarks claiming its first in-house chip beats Nvidia's GB300. Jalapeño, the inference ASIC OpenAI co-developed with Broadcom, delivered 1.5 times to 1.9 times more throughput per kilowatt and 1.7 times to 3.6 times lower end-to-end latency than Nvidia's GB200 and GB300 rack systems on SemiAnalysis's public InferenceX suite, with a 700W part going up against accelerators rated at 1,200W and 1,400W. OpenAI plans to begin deploying the chip in its own data centers later this year.
The tests covered three open models: GPT-OSS 120B, DeepSeek R1 670B, and Moonshot AI's 1-trillion-parameter Kimi K2.5, with OpenAI reporting its widest leads at low-latency operating points, where it claims 8.6 times to 104.3 times more throughput per kilowatt at the GB300's fastest previous time-between-tokens settings.

OpenAI normalized the results to each accelerator's published package TDP, though it said Jalapeño's measured sustained power stayed at or below 550W in testing. An appendix comparison using all-in utility power per accelerator, 1.18kW for Jalapeño against 2.55kW for the GB300, produces narrower gaps, as does pitting Jalapeño against a GB300 running multi-token prediction, where the peak efficiency lead shrinks to roughly 1.5 times.
Jalapeño wasn't tested against Vera Rubin, the Nvidia platform that's slated to power the first gigawatt of Nvidia systems OpenAI agreed to deploy in the second half of 2026. The chip also doesn't train models, the workload where Nvidia's hardware remains unchallenged. In addition, the major comparisons ran Jalapeño's single-token prediction against GB300 configurations doing the same, even though Nvidia deployments commonly use multi-token prediction in production. SemiAnalysis, which said it ran InferenceX with OpenAI engineers in the company's lab, described the part as "beating every Nvidia, AMD, and Google chip we have been able to test."
Each Jalapeño package, unveiled in June after a nine-month RTL-to-tapeout cycle, pairs its compute die with six HBM4 stacks, totaling 216 GiB at 15.4 TB/s. The GB300 carries 288GB of HBM3E at a 1,400W rating, so per watt of rated power, OpenAI's chip packs roughly 50% more memory. The company's Hot Chips presentation states that the main bottleneck its architecture targets is exposing aggregate HBM bandwidth, not adding more of it.
That memory is of course the tightest commodity in the semiconductor industry. Samsung, SK hynix, and Micron have sold their HBM capacity through 2027, a shortage so severe that Nvidia is reportedly testing cut-down Rubin Ultra configurations with as little as 192GB, and SK hynix CEO Kwak Noh-jung has warned that 2027 will be the worst year of the crunch. Micron told the same Hot Chips conference on August 23 that HBM consumes roughly three times the wafer area of DDR5 for equivalent capacity, a penalty that widens with each generation. Scaling Jalapeño across the 10GW deployment agreement that OpenAI signed with Broadcom last October would make the company a substantial new claimant to HBM4 supply, which Nvidia currently dominates through multi-year allocation deals with SK hynix.
A second-generation chip is approaching tapeout, expected within months, according to Bloomberg, and concept work on a third generation is underway. The first part reportedly uses a TSMC 3nm-class process, keeping OpenAI in the same wafer, memory, and advanced packaging queues as Blackwell and Rubin for the foreseeable future.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
OpenAI is procuring those inputs while deepening its financial dependence on the company it just benchmarked. On August 17, Nvidia agreed to provide up to $105 billion in financing for an OpenAI-leased data center campus in Ohio. "Nvidia is a really good partner, and we continue to need a lot of Nvidia," Richard Ho, OpenAI's vice president of hardware, told Bloomberg in an interview following the announcement.

Follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Luke James is a freelance writer and journalist. Although his background is in legal, he has a personal interest in all things tech, especially hardware and microelectronics, and anything regulatory.
-
vanadiel007 I can see this going to same way as crypto mining with video cards: replacement with ASIC.Reply
I wonder what the next big thing is going to be. Has to be something with GPU's. -
Bigshrimp More money to throw into the bottomless pit of AI. Even with the gains in performance per kilowatt, they will just throw more hardware in and it will still pull a ton of power as if there were no gains. Might eek out more performance, but that's about it.Reply -
Darkhands Can't wait till the day nvidia loses its lead in the AI race. They ditched gamers to grab all that AI pie, and they'll need to come crawling back.Reply -
bit_user I just have to point out that efficiency scaling is definitely not on Nvidia's side, here. If they reduced clockspeeds a little bit, they could save a ton of power. The reason they've been clocking their server parts so aggressively is that their hardware costs datacenter operators a lot more than the power to run & cool them. So, Nvidia is all about maximizing the performance because that lets them charge more since they just need to deliver more perf/$ than either their old hardware or competitors' systems.Reply
Ah, see? This is the problem everyone has when they think they can compete against Nvidia. Usually, it's Nvidia's previous generation they end up being competitive with. Nobody has managed to move fast enough to keep ahead of Nvida, except maybe Cerebras.The article said:Jalapeño wasn't tested against Vera Rubin, the Nvidia platform that's slated to power the first gigawatt of Nvidia systems OpenAI agreed to deploy in the second half of 2026. -
bit_user Reply
Nvidia bought Groq for the part that's most ASIC-friendly. That's also what OpenAI's new chip does. I'm sure Jalapeno is nowhere near as fast or efficient at inference, when compared to a Nvidia solution with Groq 3 LPU doing the same thing.vanadiel007 said:I can see this going to same way as crypto mining with video cards: replacement with ASIC.
I wonder what the next big thing is going to be. Has to be something with GPU's. -
alan.campbell99 More competition for fab capacity? I'd also wonder about the unit economics if said fabs are hiking prices, also being wafer scale how much of an issue defects would be.Reply
Putting aside all the other issues I have with this nonsense. -
usertests Reply
I'm not sure they've done anything that Nvidia can't copy. And it wasn't compared against Rubin.vanadiel007 said:I can see this going to same way as crypto mining with video cards: replacement with ASIC.
I wonder what the next big thing is going to be. Has to be something with GPU's.
When I think of an AI ASIC, I think of Taalas, which AMD recently acquired. You get one permanently baked smaller-sized model, with some ability to fine-tune it, running at extraordinary speeds. -
bit_user Reply
I don't really look at it like that. I think OpenAI would be buying chips, whether theirs/Broadcom's or Nvidia's. Maybe, by saving money on theirs, they can consume more wafers for the same $. So, it could be slightly higher contention for fab capacity. However, as the article points out, their solution relies on HBM, which is almost certainly the production bottleneck.alan.campbell99 said:More competition for fab capacity?
Uh, Jalapeno doesn't appear to be a wafer-scale engine. They're just showing an uncut wafer, as is traditional for these sorts of chip announcements. It's probably a first run or otherwise marginal wafer with too many defects to actually use. I guess showing the wafer is proof that it reached the production stage.alan.campbell99 said:also being wafer scale how much of an issue defects would be. -
bit_user Reply
Nvidia is somewhat chained down by the legacy of CUDA compatibility. However, the Groq LPU is not. That's the key to Rubin's competitiveness on inference workloads.usertests said:I'm not sure they've done anything that Nvidia can't copy. And it wasn't compared against Rubin. -
Trake_17 Reply
Hate to break it to you but this day will never come. The dealer has never come crawling back to the addict in all of history. Beyond that, Nvidia is in no danger of losing its footing on this front, particularly given OpenAIs dependence on Nvidia and Nvidias in estments in OpenAI.Darkhands said:Can't wait till the day nvidia loses its lead in the AI race. They ditched gamers to grab all that AI pie, and they'll need to come crawling back.